Use case – Copilot Governance
Wiiisdom for Power BI Copilot Governance
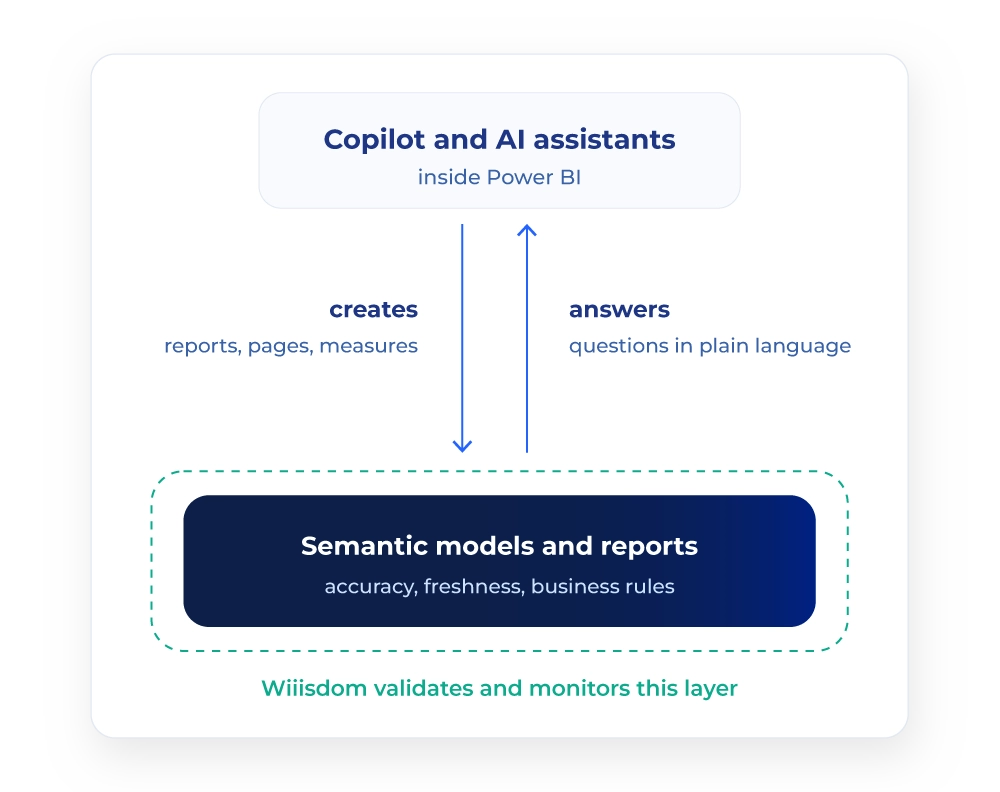
Copilot is only as good as the content it reads, and it answers with the same confidence whether the model behind it is right or wrong. Wiiisdom validates the semantic models and reports Copilot draws on, and makes their state visible before anyone builds on them.
Trusted by more than 600 leading companies and organizations
Dimensions that matter most for enterprise reporting
What it does
Confidence is not accuracy. Only testing tells them apart.
Govern what Copilot consumes
In analytics, without trust there is no adoption. Wiiisdom makes AI-driven insights reliable by rigorously quality-checking the semantic models and reports Copilot is built on. It runs data reconciliation dynamically, validates freshness, tests calculation logic at the semantic model level through DAX queries, and checks content against business rules to detect anomalies, which mitigates risk and replaces distrust with adoption.
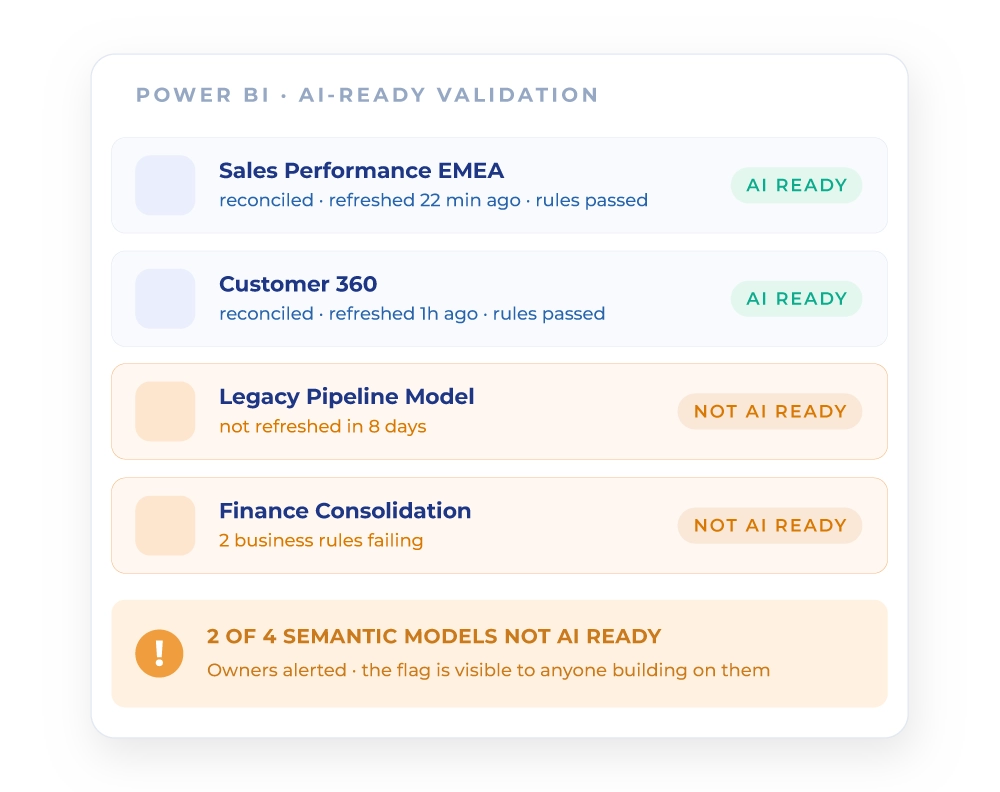
Certify the reports, flag what is AI-ready
With the proliferation of reports it is already hard to tell which ones deserve trust. Generative BI makes it harder, because producing new content becomes effortless for everyone. Wiiisdom establishes a visual standard: reliable reports carry a dynamic certification stamp, and the content that has passed accuracy, freshness, security and business-rule validation is identified at a glance. Power BI endorsement stops being a static label and becomes the output of tests that actually ran.
Keep control of what Copilot helps produce New
Copilot does not only answer questions, it builds. Reports, pages, measures and visuals now get created in minutes by people who would never have opened Power BI Desktop, and that is exactly the point: it is a real gain in efficiency. It is also a sprawl problem waiting to happen, because the volume of new content rises far faster than anyone’s ability to review it. Wiiisdom applies the same treatment to Copilot-assisted content as to anything else: it passes through the path to production, it is validated against the source of truth, and it carries a state anyone can see. The efficiency is kept, the sprawl is not.
Our point of view
AI does two things to your analytics. Both of them need governing.
Copilot is only as good as the content it reads, and it answers with the same confidence whether the model behind it is right or wrong. Wiiisdom validates the semantic models and reports Copilot draws on, and makes their state visible before anyone builds on them.
The payoff
From AI answers you have to double-check to AI answers built on validated content.
An AI assistant cannot judge whether the model it just read is accurate or current. It answers anyway, and it builds on it just as readily. Validation and certification give that content a verifiable state, on the way in and on the way out.
- Copilot answers just as confidently from a wrong model as from a right one
- Nobody can tell whether the model behind an insight refreshed this morning or last month
- An error in a semantic model is amplified instantly, across every answer that uses it
- Copilot-assisted reports multiply faster than anyone can review them
- Users double-check AI output manually, which removes the reason to use it
- Semantic models reconciled, validated against business rules, and monitored continuously
- Freshness validated per model, so nobody builds an insight on a stale refresh
- A visible AI-ready flag tells users and builders which content qualifies
- Copilot-assisted content routed through the same path to production as everything else
- Adoption rests on evidence, because the state of the content is knowable
“Analytics governance is now required, not a nice-to-have”
Gartner®, Hype Cycle™ for Data and Analytics Governance, 2024, by Guido De Simoni, Andrew White, Saul Judah, 18 June 2024. Gartner and Hype Cycle are registered trademarks of Gartner, Inc. and/or its affiliates in the U.S. and internationally and are used herein with permission. All rights reserved.
Coming soon
Judging how likely an answer is to be right.
Governing what Copilot reads and what Copilot builds covers the content. The next step is the answer itself.
An answer cannot be trusted because it reads well, and it cannot be checked by asking another model whether it looks correct. Wiiisdom is building a deterministic evaluation of Copilot responses: a repeatable, rule-based assessment of how likely a given answer is to be right, producing a signal you can act on, with the same alerting, the same ownership and the same audit trail as every other check on this page.
It is the piece that closes the loop between governing the input and trusting the output.
Not generally available. Talk to us if you want to be part of the early program.
Agentic analytics governance
The whole platform serves this use case.
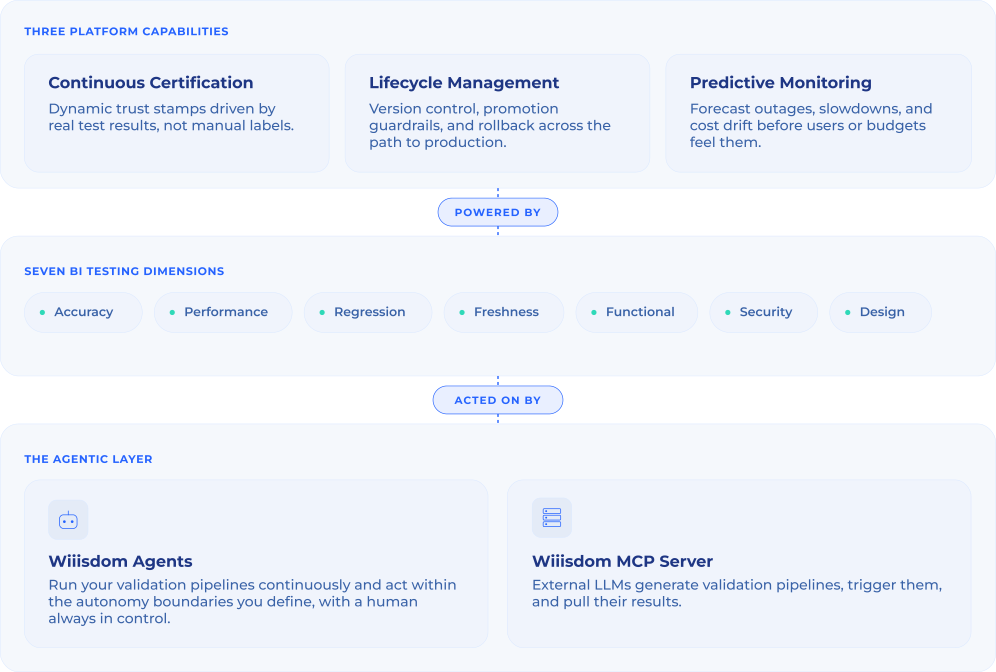
Testing is the foundation. It powers the three capabilities of the Wiiisdom platform, which agents and external AI systems act on continuously.
Keep exploring